Pick Datadog if your application visibility depends on infrastructure depth, Kubernetes, logs, security signals, and multi-cloud operations; pick New Relic if your team wants strong application performance monitoring with simpler pricing and clear developer workflows. Both can show what broke, where it broke, and who should fix it. The real difference is how each platform turns raw signals into useful answers.
TLDR: Monitoring tells you that something is wrong, telemetry is the data that proves it, and observability helps you understand why it happened. For example, an ecommerce team seeing checkout latency jump from 320 ms to 1.8 seconds needs traces, logs, metrics, and user impact in one view. Datadog is often stronger for complex infrastructure and operations teams; New Relic is often easier for app teams that want quick setup and useful APM dashboards. In a 40-service environment, the better tool is usually the one that cuts incident triage from 45 minutes to under 15.
Monitoring, telemetry, and observability are not the same thing
Monitoring is the classic alerting layer. It watches known signals and tells you when a threshold has been breached. CPU above 90%. Error rate above 5%. API latency over 800 ms. Monitoring is useful, but it can be narrow. It answers, “Is something wrong?”
Telemetry is the raw material. It includes metrics, logs, traces, events, profiles, real user data, synthetic checks, and infrastructure metadata. Without telemetry, your dashboards are just empty boxes. With too much unstructured telemetry, your team drowns in noise.
Observability is the ability to ask new questions about your systems without shipping new code every time. It connects signals across services, hosts, containers, databases, queues, browsers, and mobile apps. Good observability answers, “Why is this happening, how bad is it, and what changed?”
Where Datadog shines
Datadog is built for teams that care about the full stack. It started strong in infrastructure monitoring and expanded into APM, logs, user monitoring, cloud security, network monitoring, incident management, database monitoring, and more. If your application runs across Kubernetes, AWS, Azure, GCP, containers, serverless functions, and managed databases, Datadog gives you a wide operational view.
The platform is especially good at correlation. A slow endpoint can be tied to a trace, a noisy pod, a database query, a deployment marker, and a related log stream. That saves time during incidents. Instead of jumping through six vendor tabs, you can follow the trail in one place.
- Best fit: SRE teams, platform teams, DevOps groups, and enterprises with complex infrastructure.
- Strong points: infrastructure metrics, Kubernetes visibility, log analytics, cloud integrations, security monitoring, and alerting flexibility.
- Weak points: pricing can grow fast, setup can feel sprawling, and dashboards may need tuning before they become truly useful.
Honestly, it feels like Datadog can show you everything, including things you did not ask for. That is powerful during a serious outage. It is also annoying when a simple investigation turns into ten tabs, five filters, and a billing question nobody wants to answer.
Where New Relic shines
New Relic has deep roots in application performance monitoring. It is often loved by developers because it makes application behavior visible without requiring a huge ops project. Service maps, transaction traces, database calls, distributed tracing, error tracking, browser monitoring, and mobile monitoring are all core parts of the experience.
New Relic’s strength is clarity. A developer can open a service, inspect slow transactions, view related errors, and see how users are affected. It also offers strong OpenTelemetry support, which matters for teams that do not want to be trapped in a single vendor’s instrumentation style.
- Best fit: application teams, engineering managers, product engineering groups, and SaaS companies focused on user experience.
- Strong points: APM, distributed tracing, user experience analytics, OpenTelemetry support, and approachable dashboards.
- Weak points: infrastructure depth may feel lighter than Datadog in large operations setups, and advanced querying still takes practice.
The catch is that New Relic can feel clean until your system gets messy. Once dozens of services, queues, cron jobs, lambdas, and third-party APIs join the party, teams still need careful naming, tagging, and alert rules. No tool saves you from bad signal hygiene.
Application visibility: what actually matters
Application visibility is not just about pretty charts. It is about reducing uncertainty. During an incident, your team needs to know five things fast:
- What changed? A deploy, config edit, traffic spike, feature flag, or dependency issue.
- Who is affected? All users, one region, one customer tier, or one browser type.
- Where is the fault? Frontend, API gateway, service layer, database, cache, queue, or third-party call.
- How severe is it? Latency, errors, failed checkouts, lost revenue, or missed service targets.
- What should happen next? Rollback, scale, restart, tune a query, or call the vendor.
Datadog tends to win when that question spans infrastructure and operations. New Relic tends to win when the question starts inside the application and user journey. Both can cross those lines, but each has a natural comfort zone.
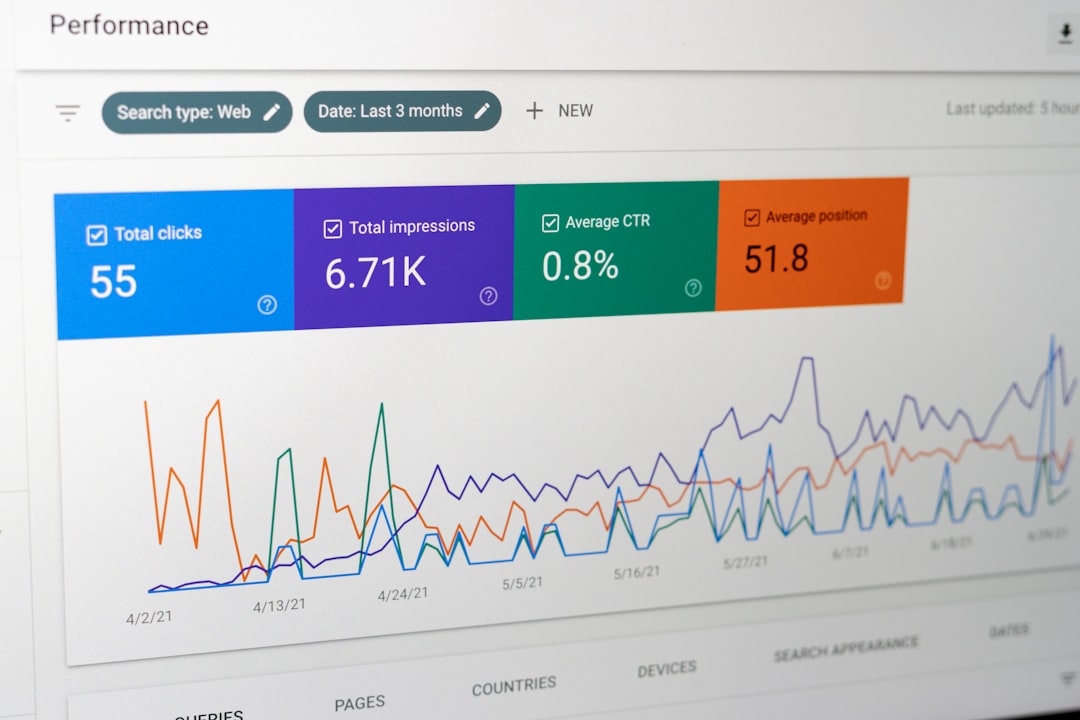
Datadog vs New Relic: practical comparison
Setup: New Relic often feels faster for app teams. Install an agent, connect services, and useful APM data appears quickly. Datadog setup can take more planning, especially when logs, infrastructure, Kubernetes, security, and APM are all enabled.
Dashboards: Datadog dashboards are highly flexible and strong for operations centers. New Relic dashboards are clean and helpful for application owners. If executives want service health, either works. If SREs need container-level details, Datadog may feel richer.
Tracing: Both platforms support distributed tracing. Datadog offers strong trace-to-log and trace-to-infrastructure correlation. New Relic offers developer-friendly transaction views and strong OpenTelemetry paths.
Logs: Datadog is widely used for log analytics, but costs can rise with ingestion volume. New Relic also handles logs well, and its pricing model may be easier for some teams to predict. Expect to waste time on log filtering if nobody sets retention rules, sampling, and tag standards early.
Pricing: This is where evaluation gets real. Datadog pricing can become complicated as teams add APM, logs, synthetics, RUM, database monitoring, security, and custom metrics. New Relic’s pricing is often seen as simpler, especially with usage-based data ingest and user-based options. Still, either tool can get expensive if teams send every debug log forever.
A short scenario
A subscription video app sees buffering complaints jump by 32% after a Friday release. Monitoring detects an error rate spike. Telemetry shows browser timing, CDN logs, API traces, container metrics, and database latency. Observability connects the dots: a new recommendation API call added 600 ms to page load for users in Europe.
In Datadog, the operations team might start from a regional latency alert, inspect Kubernetes pods, compare deployment markers, open related traces, and check CDN logs. In New Relic, developers might start from browser monitoring, move into transaction traces, inspect the slow service, and compare performance before and after the release. Both routes can work. The faster one depends on how your team thinks.
The role of OpenTelemetry
OpenTelemetry is changing this debate. It gives teams a vendor-neutral way to collect traces, metrics, and logs. That matters because instrumentation is expensive to redo. If you instrument services with OpenTelemetry, you can send data to Datadog, New Relic, or another backend with less pain.
New Relic has made OpenTelemetry a visible part of its story. Datadog also supports it, while still encouraging use of its own agents for richer features. If vendor flexibility is a major concern, ask hard questions during trials. Check which features work with OpenTelemetry data and which require native agents.
How to choose without regret
Do not start with feature lists. Start with your incidents. Pull three recent outages and replay them in both platforms. Measure time to answer basic questions. How long to find the failing service? How long to see customer impact? How long to identify the change that caused it?
Choose Datadog if your biggest pain is operational complexity. It is a strong fit when infrastructure, containers, logs, networks, and cloud services are part of every incident. Choose New Relic if your biggest pain is application performance and developer clarity. It is a strong fit when teams need fast APM insight, clean traces, and user-focused diagnostics.
The best observability platform is not the one with the longest feature page. It is the one your team actually uses at 2:13 a.m., under pressure, without guessing. Datadog and New Relic can both get you there. The right choice depends on whether your visibility problem starts closer to the infrastructure layer or closer to the application code.